GKE becomes more elastic: Scale to zero, save costs, and keep workloads responsive
GKE 1.37 adds native scale‑to‑zero, letting workloads drop to zero replicas and resume instantly from capacity buffers. The blog details HPA integration, removing KEDA operators and reducing config complexity, while cutting idle cost for batch and dev workloads.
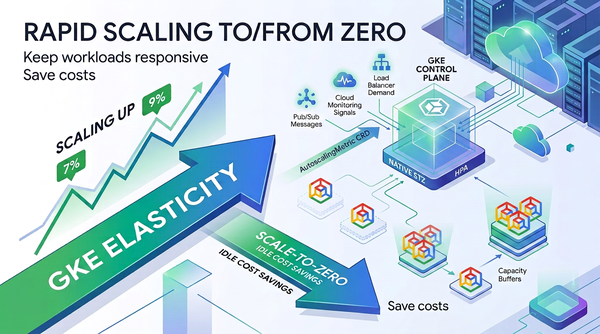
Google Kubernetes Engine version 1.37 introduced a native capability that lets workloads shrink to 0 replicas and be revived instantly from capacity buffers. The feature relies on the HorizontalPodAutoscaler combined with the AutoscalingMetric custom resource, which can read external signals such as Pub/Sub undelivered‑message counts. By setting minReplicas: 0 in the HPA, the control plane can terminate pods when metrics dip below a threshold and restart them as soon as work appears. Eliminating the need for KEDA operators removes thousands of lines of configuration and reduces operational toil. Capacity buffers provide a small pool of warm compute that cuts the typical 60‑90 second node‑provisioning delay to an instant start, keeping idle cost near zero while preserving rapid responsiveness. The integration also streamlines security and latency by using Google Managed Service for Prometheus directly, without third‑party adapters. Google’s team notes that the exact latency improvement varies with workload characteristics and that the balance between active and standby buffers still requires tuning. It is also unclear how the approach will perform at extreme scale beyond the current testing limits, and further data are needed to confirm cost savings for very large fleets.