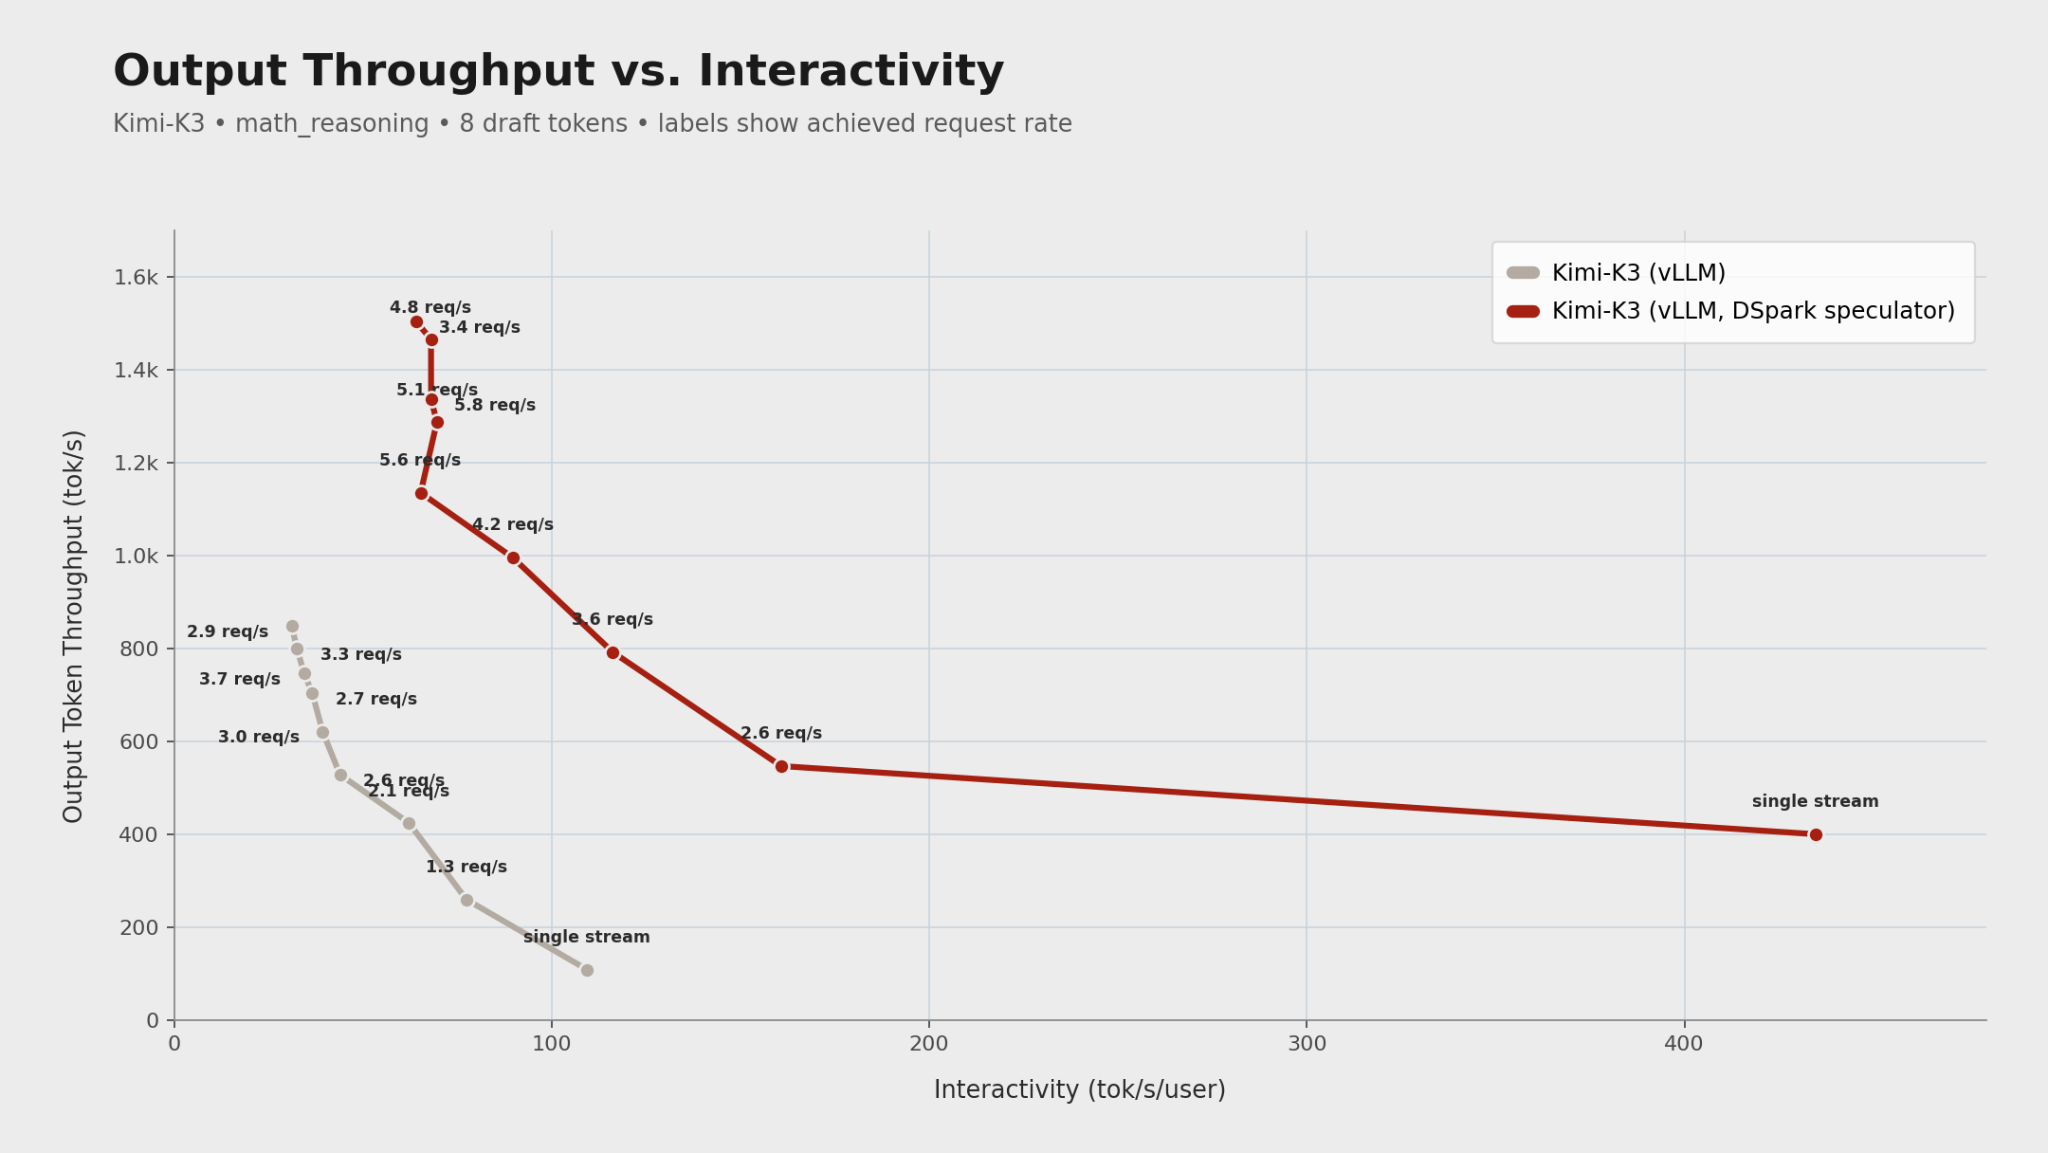
How we trained the fastest DSpark for Kimi-K3 using GB300 NVL72
vLLM documents a DSpark speculator for Kimi K3 that boosts single-stream math reasoning speed from 110 to 435 tokens per second. The library supports training and packaging draft models in Hugging Face format for direct vLLM loading. Validated on Qwen3.6 and Gemma-4, this update improves concurrent output throughput by up to 3.5x at matched interactivity levels.